Skymizer Launches HTX301 PCIe AI Accelerator Running 700B LLMs at 240W on 28nm
The AMW Read
New chip-level product using legacy process and commodity memory to run 700B models locally; meaningfully updates the inference hardware baseline and signals potential shift in accelerator economics.

Skymizer Launches HTX301 PCIe AI Accelerator Running 700B LLMs at 240W on 28nm
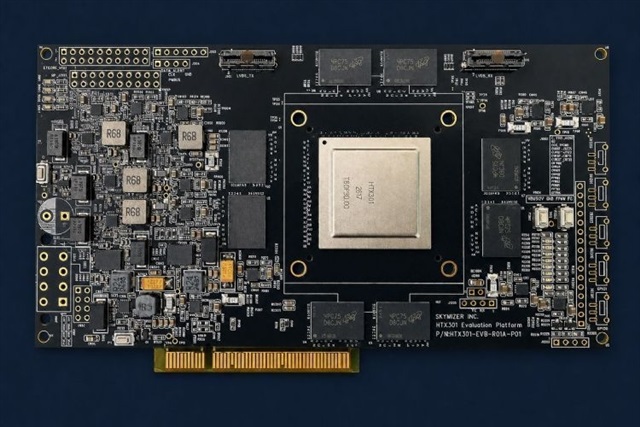
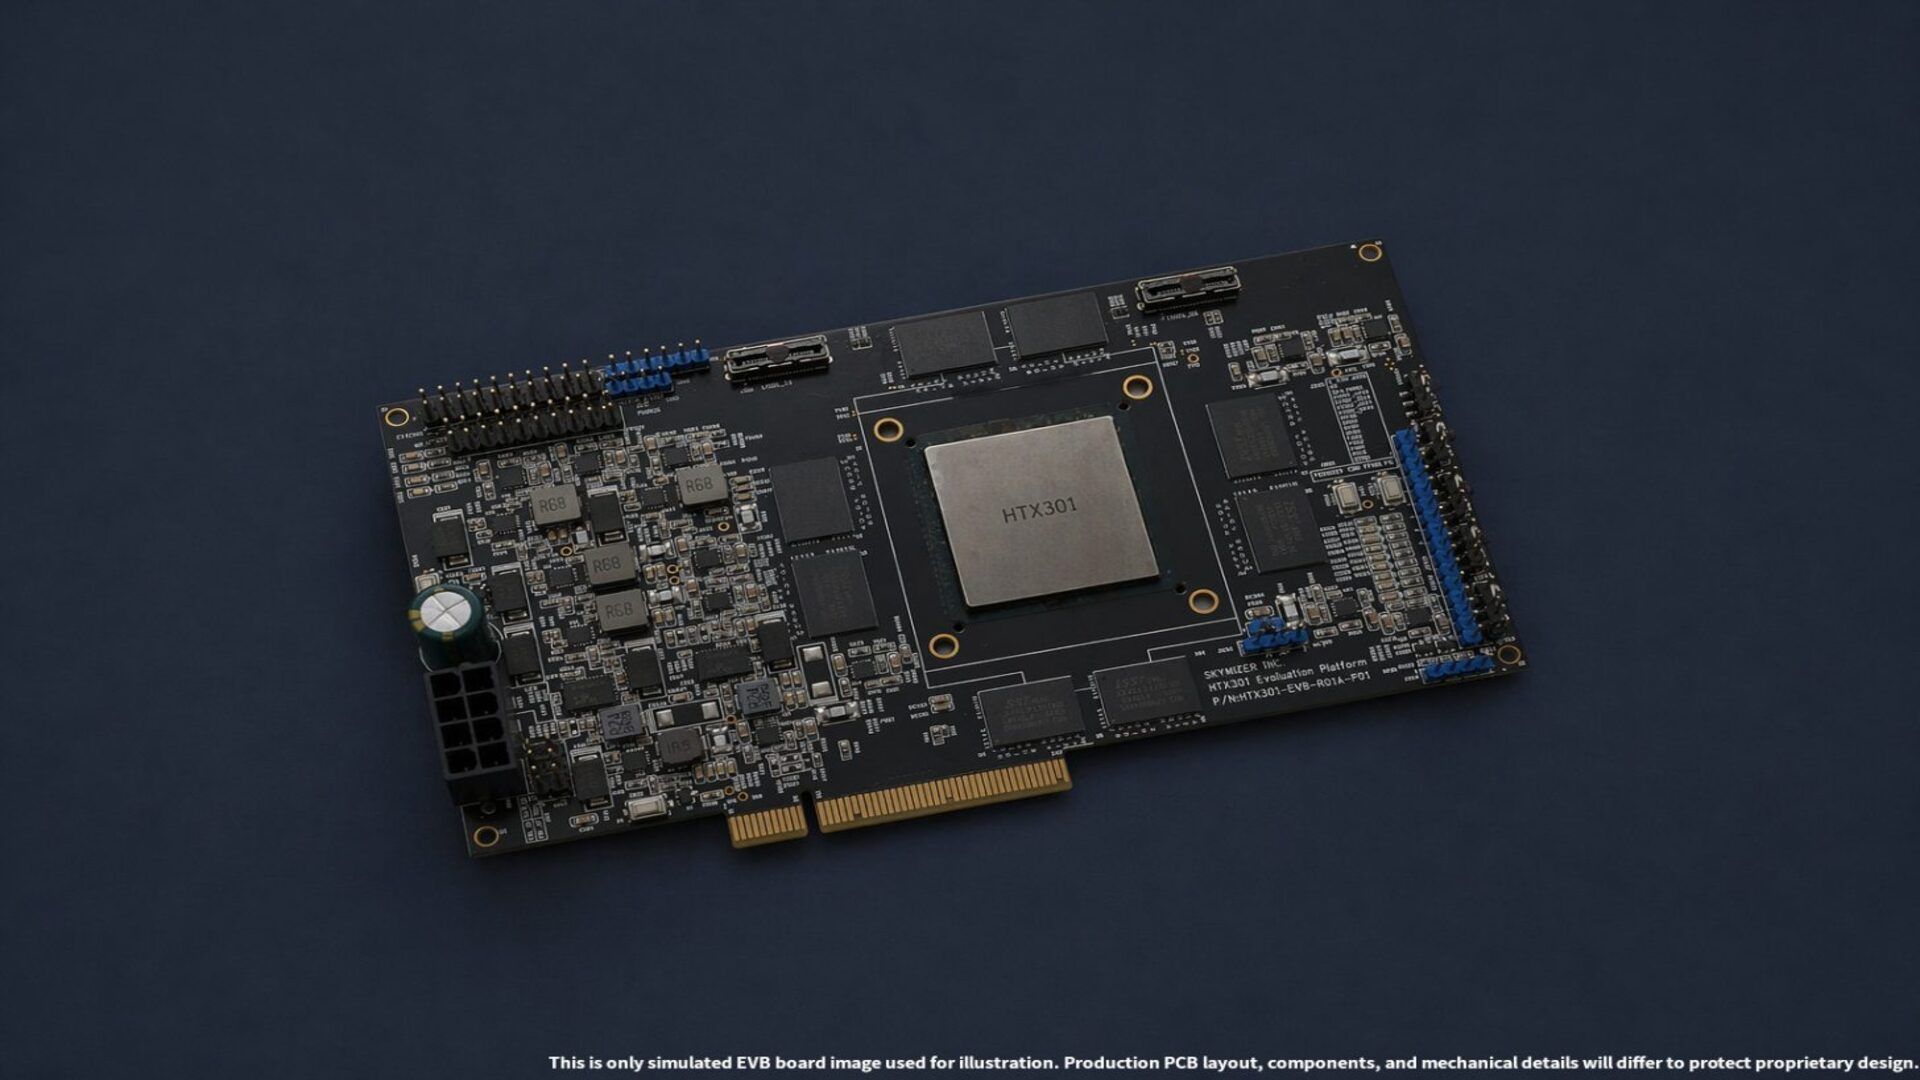
Taiwanese startup Skymizer has unveiled the HTX301, a PCIe AI accelerator card that can run language models with up to 700 billion parameters on a single device, drawing only 240 watts. The card achieves this using older 28nm process chips and standard LPDDR4/LPDDR5 memory rather than expensive HBM or GDDR, enabling 384GB of total memory per card. This design directly targets the high cost and power consumption of hyperscale GPU clusters for local inference.
Why it matters: This product directly challenges the hyperscaler-distribution moat that Nvidia and AMD have built around high-end AI inference. By proving that 700B-parameter models can run locally on legacy 28nm silicon with commodity memory, Skymizer opens a potential cost-arbitrage path for enterprises that want on-premise inference without massive GPU capital expenditure. If validated at scale, this could push inference hardware toward cost-optimized, low-power architectures rather than the shrinking-node, high-bandwidth-memory trajectory that currently dominates the accelerator market.
Industry experts note that Skymizer's approach exploits the fact that inference workloads are memory-bandwidth bound, not compute bound. Using cheap DDR4 and an older process node allows dramatic per-chip cost reduction while the large on-card memory handles the parameter footprint of 700B models. The key open question is whether real-world inference latency and throughput meet enterprise SLAs. If the HTX301 can deliver acceptable performance for batch or edge use cases, it could reshape the inference hardware segment, pressuring incumbents to offer lower-cost alternatives or risk losing the on-premise enterprise market.