More unveils TIDE framework for faster LLM inference
The AMW Read
TIDE adds a company-reported inference optimization, but its maximum benchmark results lack enough detail to establish broader impact.
More unveils TIDE framework for faster LLM inference
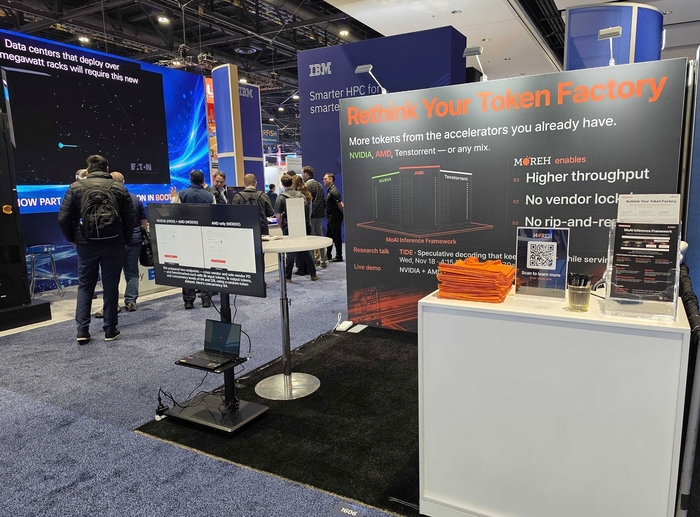
More introduced TIDE, a framework designed to improve large language model inference, at Supercomputing 2026 in Chicago. The company said its research showed up to 1.66 times the throughput of inference without speculative decoding. It also reported that TIDE reduced the time needed to train an auxiliary model by up to 3.02 times compared with an existing online training approach. The reported figures are maximum results; the source does not specify the test configurations.
TIDE addresses an inference-serving tradeoff: speculative decoding can accelerate generation, but its benefit depends on how accurately a smaller model predicts tokens for the larger model to verify. More says TIDE progressively trains that smaller model using intermediate hidden states generated during inference. This avoids a separate run of the larger model to produce training data, according to the company. The work places More in the inference software layer, where providers compete to increase useful output from available computing resources.
For builders assessing TIDE, the relevant question is whether its throughput gains hold for their models, request patterns, and hardware. The source does not provide those benchmark details or independent validation, so the maximum result alone is insufficient to estimate production savings. More says it also develops software for operating GPUs from different manufacturers and is working on a token factory operating system for allocating heterogeneous accelerator resources.