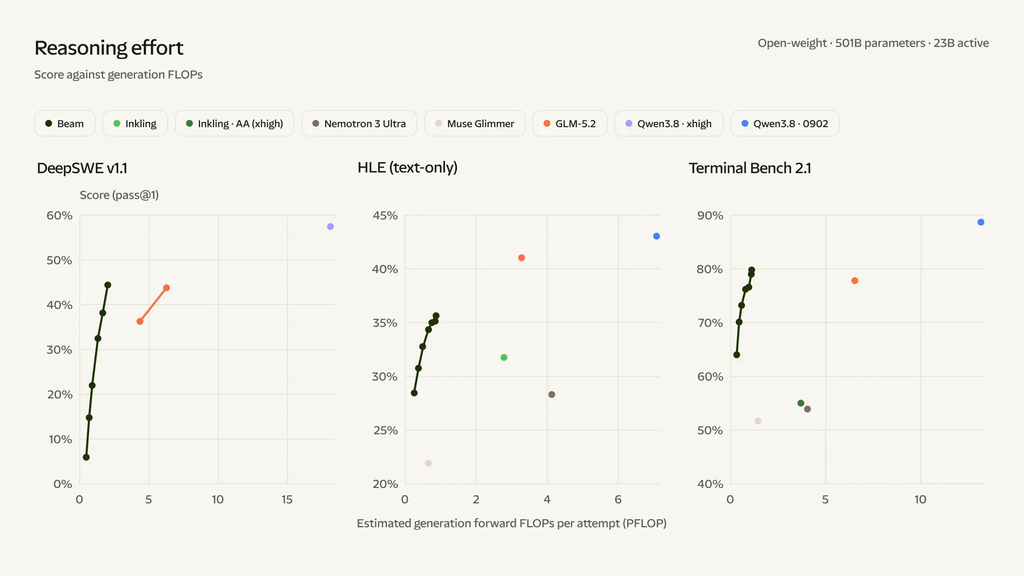
Reflection releases Beam open weights with a focus on using fewer tokens
The AMW Read
Released weights and enterprise installation partners meaningfully advance Reflection's offering, with segment-level implications if its task-efficiency claims withstand independent testing.
Reflection releases Beam open weights with a focus on using fewer tokens
Reflection released the weights for Beam, a 501-billion-parameter model with 23 billion active parameters per token. The company says reinforcement learning trained Beam to complete tasks with fewer tokens. The launch includes Apache 2.0-licensed deployment software. Reflection says quantized versions can run on eight-GPU servers, while Dell and HPE will install the model on customer hardware. Shinsegae Group is also working with Reflection on shopping agents.
The release adds a deployable offering to the open-weight foundation-model market, pairing model access with enterprise installation channels. Its efficiency proposition centers on reducing the tokens needed to finish a task, making cost per completed task the relevant measure for buyers. That distinction matters for agent workloads, where repeated model calls can accumulate costs. Dell and HPE provide a route onto customer hardware, but the reported installation arrangements and shopping-agent work do not establish Beam's performance or commercial adoption at scale.
Builders evaluating Beam should test its token-efficiency claim against task completion quality, latency, and total serving cost on their own workloads. Fewer generated tokens would offer limited value if retries or failed actions offset the savings. For investors, the concrete question is whether released weights, deployment software, and hardware partners translate into repeatable enterprise use. The supplied report includes no independent evaluation establishing that Beam delivers a lower cost per successful task.