HyperAccel to Demonstrate Eight-LPU AI Inference Server at SC26
The AMW Read
The server demonstration updates an inference-chip competitor, but its reported efficiency gains need validation in customer workloads.
HyperAccel to Demonstrate Eight-LPU AI Inference Server at SC26
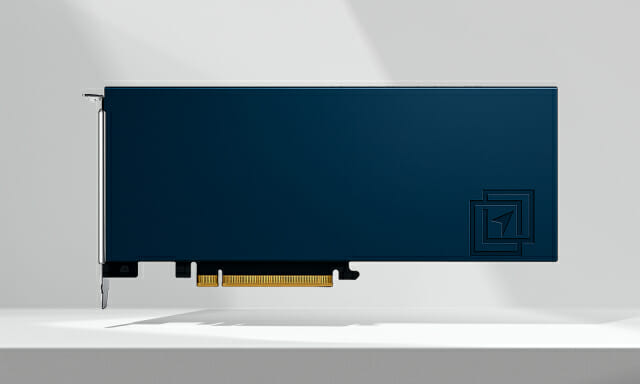
HyperAccel plans to demonstrate an AI inference server equipped with eight of its LLM processing units, or LPUs, at SC26 in Chicago. The system will run large language models through a real-time connection to a server operating in South Korea. The event runs from November 17 to 19.
The announcement places HyperAccel among chipmakers competing to lower the cost and power consumption of AI inference. The company says its LPU server achieved more than 3.5 times the tokens per watt and per dollar of a system based on Nvidia's RTX Pro 6000 Blackwell Server Edition GPU. The comparison used models including Qwen3-32B and Llama3-70B. The reported results do not establish performance across other workloads or deployment settings.
For infrastructure buyers, the test is whether those efficiency gains hold under their own model, latency, and utilization requirements. HyperAccel says its LPU pairs LPDDR5X memory with a proprietary dataflow architecture and draws 250 watts per card, versus 600 watts for the comparison GPU. The company plans to discuss technical validation and potential cooperation with server manufacturers, cloud providers, and infrastructure companies. It has not announced a resulting agreement.